
USE CASE
Preventing Unwanted Content Scraping
Protect IP, pricing info, and infrastructure from automated harvesting.
Content scraping has evolved from simple scripts extracting HTML to a sophisticated, automated operation targeting web and mobile apps, APIs, and web endpoints. As digital businesses rely more heavily on APIs to deliver data-rich experiences, attackers have shifted their tactics accordingly, exploiting these endpoints to harvest valuable content and data. Understanding how scraping works and its impacts is critical to designing stronger defenses.
What is Content Scraping?
Content scraping is the automated extraction of data from websites, apps, or APIs—often without consent. While some scraping is benign, such as search engine crawlers indexing your content, malicious scraping can target:
- Pricing and product details for unfair competitive advantage
- Intellectual property and sensitive information
- User data for fraud and abuse
Today, most structured data resides behind APIs, which means that scraping has shifted from targeting front end HTML pages to exploiting backend endpoints. This evolution turns scraping from a simple front-end nuisance into a direct and complex API security challenge.
How Content Scraping Works
Scraping has moved far beyond sending basic HTTP requests. Modern scraping operations use a combination of advanced, distributed techniques designed to mimic human behavior and evade detection:
1
Headless browsers and automation frameworks
simulate human interaction, load JavaScript, manage cookies, and bypass simple anti-bot defenses
2
API exploitation
from attackers reverse engineer mobile apps or other applications to identify hidden or undocumented APIs and query them directly
3
Residential proxies
enable scrapers to route traffic through massive proxy networks to disguise requests as originating from real users, bypassing IP-based blocking
4
CAPTCHA
bypass via AI-powered solvers and human CAPTCHA farms make traditional access challenges far less effective
How Agentic AI Changes Content Scraping
Agentic AI amplifies scraping into autonomous, adaptive, and highly efficient attacks. Unlike traditional scrapers, AI agents can reason about their environment and adjust tactics instantly—rotating proxies, modifying payloads, and bypassing defenses without human input. This makes rule-based detection far less effective. AI-powered scraping capabilities include:

Smarter Data Collection
Analyzing and contextualizing scraped data into actionable intelligence in real time

Human-like Simulation
Generating thousands of realistic browsing patterns to evade behavioral detection

API Reverse-Engineering
Bypassing anti-bot protections and crafting adaptive payloads tailored to each target
By combining these techniques, agentic AI transforms scraping from a static nuisance into a constantly evolving threat—rendering rate limits, WAF rules, and basic bot detection largely ineffective.
Impacts of Content Scraping

Intellectual Property Theft
Proprietary datasets, curated research, and premium content can be stolen and republished without consent.

Competitive Price Undercutting
E-commerce competitors scrape product catalogs and pricing APIs to dynamically adjust their prices, eroding margins.

Infrastructure Strain
Excessive scraping drives up API and hosting costs, slows response times, and disrupts legitimate user experiences.

Fraud Enablement
Scraped data often fuels downstream attacks like credential stuffing, phishing, and account takeover campaigns.
Real-World Examples
Data from 500 million LinkedIn users was scraped and later a 700 million profile dataset appeared for sale online.
Anthropic/Reddit
Reddit filed a lawsuit against the AI company Anthropic, accusing it of illegally scraping millions of Reddit user comments to train its Claude chatbot without a licensing agreement or user consent.
Dell
Attackers posed as a partner company and used Dell’s partner portal API to scrape approximately 49 million customer records, exposing sensitive personal data.
How Cequence Prevents Content Scraping
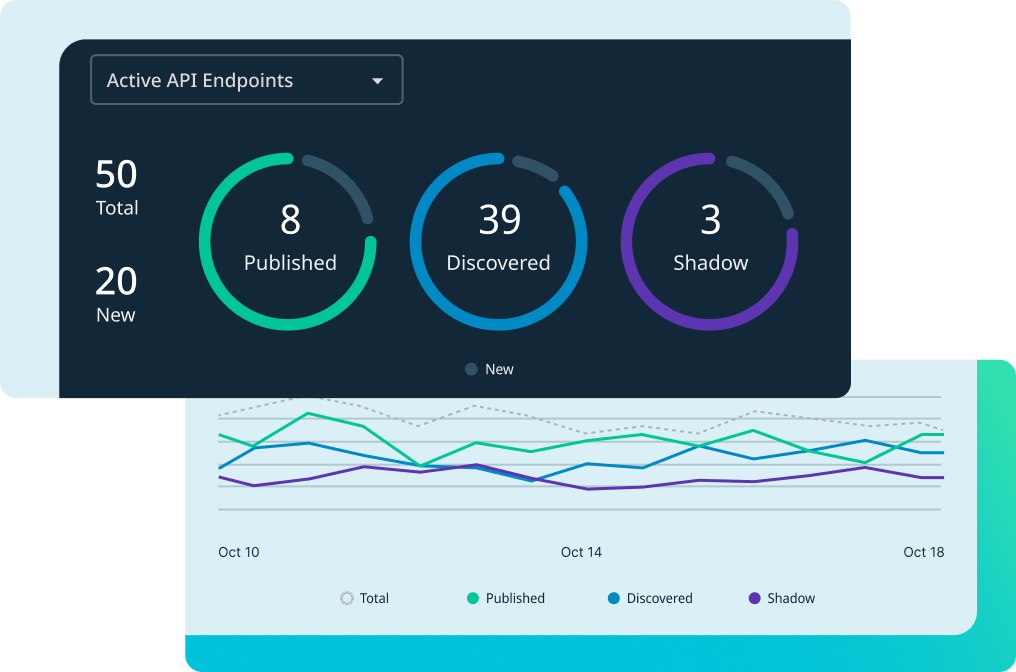
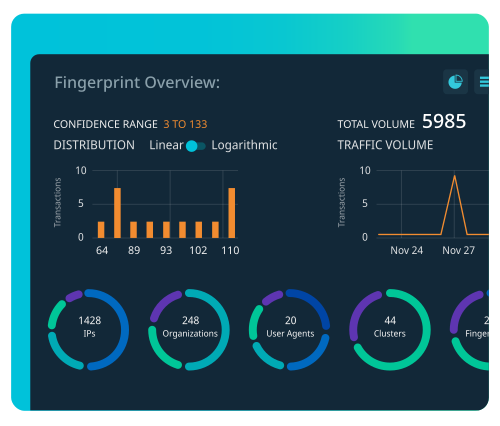
Cequence protects against scraping by combining API discovery, behavioral bot detection, and adaptive threat prevention. Unlike traditional WAFs or IP-based blocking, Cequence focuses on behavioral intent-based analysis at the API and bot automation layers, accurately distinguishing legitimate traffic from malicious scraping campaigns.
API Discovery & Inventory
Behavioral Bot Detection
Real-Time Threat Prevention
Additional Resources
Cequence Security application and API protection experts will show you how we can help you improve your security posture with a personalized demo. Nothing to deploy. All we need is your email.
Get Started Now